
ACAI — Chapter 4: Adaptive Memory System
4.1 Objective
Chapter 3 introduced Retrieval-Augmented Generation (RAG).
ACAI can now:
User
 ↓
Planner
 ↓
Retrieval
 ↓
Relevant Context
 ↓
Model
 ↓
Response
However, the system still has an important limitation:
It does not remember useful information from previous interactions.
Chapter 4 introduces an Adaptive Memory System.
The new architecture becomes:
User
 ↓
API
 ↓
Orchestrator
 ├── Planner
 ├── Memory
 ├── Retrieval
 └── Model
 ↓
Response
The purpose is not to save everything forever.
A practical memory system should decide:
What is worth remembering?
What should remain temporary?
What should be retrieved?
When should old information be updated?
When should information be discarded?
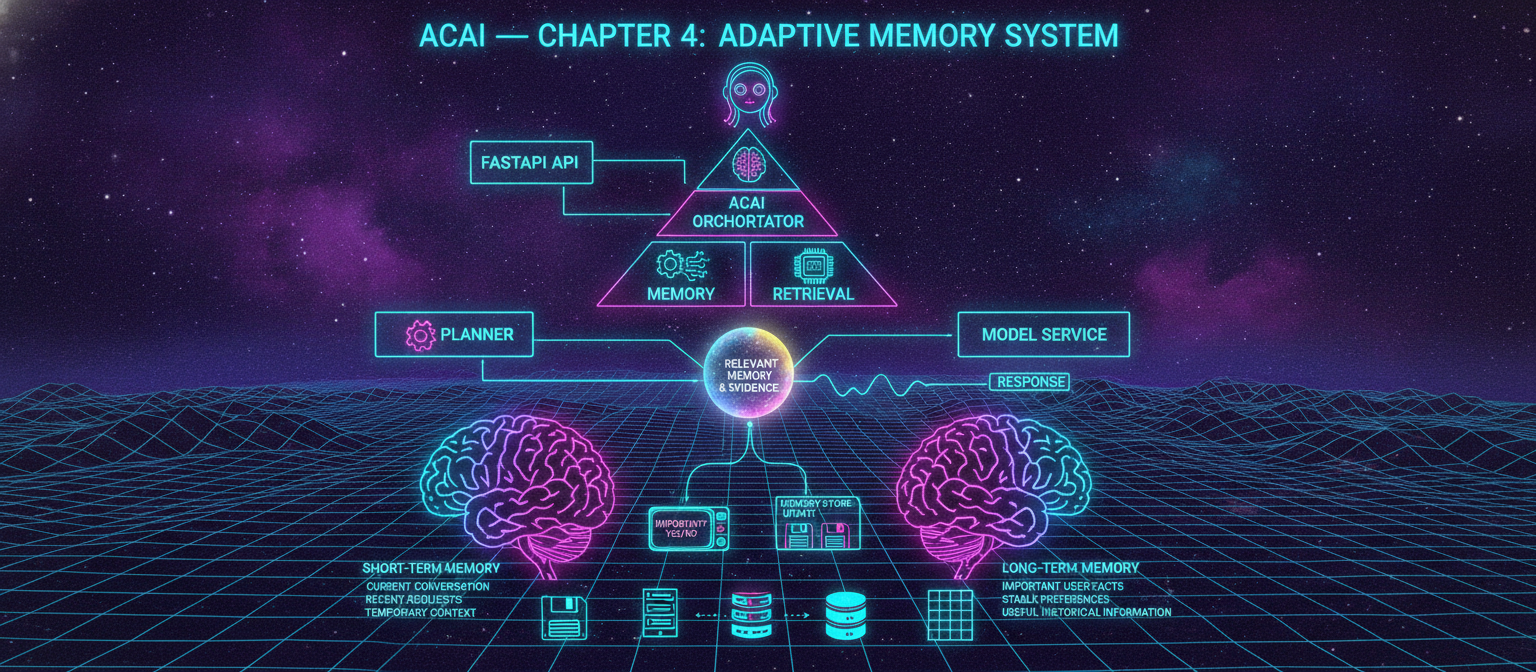
4.2 Memory Architecture
We will begin with two levels of memory:
Short-Term Memory
        │
        ├── Current conversation
        ├── Recent requests
        └── Temporary context

Long-Term Memory
        │
        ├── Important user facts
        ├── Stable preferences
        └── Useful historical information
The first implementation will use local storage.
Later it can be replaced with Redis, PostgreSQL, SQLite, or another production database.
4.3 Complete Memory Flow
                         USER
                           │
                           ▼
                      FastAPI API
                           │
                           ▼
                   ACAI Orchestrator
                           │
              ┌────────────┼────────────┐
              ▼            ▼            ▼
           Planner       Memory      Retrieval
              │            │            │
              │            ▼            │
              │       Relevant Memory   │
              │            │            │
              └────────────┼────────────┘
                           ▼
                     Model Service
                           │
                           ▼
                        Response
                           │
                           ▼
                    Memory Update
4.4 Memory Data Model
Create:
app/services/memory.py
Start with a memory record.
from dataclasses import dataclass
from datetime import datetime


@dataclass
class MemoryItem:
    memory_id: str
    content: str
    memory_type: str
    importance: float
    created_at: datetime
    updated_at: datetime
Each memory contains:
memory_id
content
memory_type
importance
created_at
updated_at
4.5 Memory Store
Add:
class MemoryStore:

    def __init__(self) -> None:
        self.items: dict[str, MemoryItem] = {}

    def add(self, item: MemoryItem) -> None:
        self.items[item.memory_id] = item

    def get(self, memory_id: str) -> MemoryItem | None:
        return self.items.get(memory_id)

    def delete(self, memory_id: str) -> bool:

        if memory_id not in self.items:
            return False

        del self.items[memory_id]

        return True

    def all(self) -> list[MemoryItem]:
        return list(self.items.values())

    def clear(self) -> None:
        self.items.clear()
This provides a minimal in-memory database.
4.6 Memory Importance
Not every message should become long-term memory.
For example:
"Hello"
usually has low memory value.
But:
"I prefer Python for backend development."
may be useful later.
We therefore introduce an importance score.
def calculate_importance(
    content: str,
) -> float:

    text = content.lower()

    score = 0.1

    important_terms = [
        "prefer",
        "always",
        "usually",
        "my project",
        "remember",
        "important",
        "use",
        "goal",
    ]

    for term in important_terms:

        if term in text:
            score += 0.15

    if len(content.split()) > 20:
        score += 0.1

    return min(score, 1.0)
This is a prototype heuristic.
It should not be treated as a scientifically validated memory-importance model.
4.7 Memory Service
Now create the complete service.
from dataclasses import dataclass
from datetime import datetime
from uuid import uuid4


@dataclass
class MemoryItem:
    memory_id: str
    content: str
    memory_type: str
    importance: float
    created_at: datetime
    updated_at: datetime


class MemoryStore:

    def __init__(self) -> None:
        self.items: dict[str, MemoryItem] = {}

    def add(self, item: MemoryItem) -> None:
        self.items[item.memory_id] = item

    def get(
        self,
        memory_id: str,
    ) -> MemoryItem | None:

        return self.items.get(memory_id)

    def delete(
        self,
        memory_id: str,
    ) -> bool:

        if memory_id not in self.items:
            return False

        del self.items[memory_id]

        return True

    def all(self) -> list[MemoryItem]:
        return list(self.items.values())

    def clear(self) -> None:
        self.items.clear()


def calculate_importance(
    content: str,
) -> float:

    text = content.lower()

    score = 0.1

    important_terms = [
        "prefer",
        "always",
        "usually",
        "my project",
        "remember",
        "important",
        "use",
        "goal",
    ]

    for term in important_terms:

        if term in text:
            score += 0.15

    if len(content.split()) > 20:
        score += 0.1

    return min(score, 1.0)


class MemoryService:

    def __init__(self) -> None:
        self.store = MemoryStore()

    def remember(
        self,
        content: str,
        memory_type: str = "general",
    ) -> MemoryItem:

        now = datetime.utcnow()

        item = MemoryItem(
            memory_id=str(uuid4()),
            content=content.strip(),
            memory_type=memory_type,
            importance=calculate_importance(
                content
            ),
            created_at=now,
            updated_at=now,
        )

        self.store.add(item)

        return item

    def search(
        self,
        query: str,
        top_k: int = 5,
    ) -> list[MemoryItem]:

        query_words = {
            word.lower().strip(".,!?;:")
            for word in query.split()
            if word.strip()
        }

        scored = []

        for item in self.store.all():

            memory_words = {
                word.lower().strip(".,!?;:")
                for word in item.content.split()
            }

            overlap = len(
                query_words & memory_words
            )

            if overlap > 0:

                score = (
                    overlap
                    + item.importance
                )

                scored.append(
                    (score, item)
                )

        scored.sort(
            key=lambda item: item[0],
            reverse=True,
        )

        return [
            item
            for _, item in scored[:top_k]
        ]

    def build_context(
        self,
        query: str,
        top_k: int = 5,
    ) -> str:

        memories = self.search(
            query=query,
            top_k=top_k,
        )

        if not memories:
            return ""

        return "\n\n".join(
            f"[Memory]\n{item.content}"
            for item in memories
        )


memory_service = MemoryService()
4.8 Memory Retrieval
Suppose the system remembers:
The user prefers Python for backend development.
Later the user asks:
"What language should I use for my backend?"
The memory layer searches previous memories.
Conceptually:
Query
 ↓
Memory Search
 ↓
Relevant Memory
 ↓
Context
 ↓
Model
The model can then use the retrieved memory as context.
4.9 Integrating Memory with the Model
Update app/services/model_service.py:
from app.config import settings


class ModelService:

    def __init__(self) -> None:
        self.provider = settings.model_provider
        self.model_name = settings.model_name

    async def generate(
        self,
        prompt: str,
        context: str = "",
        memory: str = "",
    ) -> str:

        if self.provider == "mock":

            return self._mock_generate(
                prompt=prompt,
                context=context,
                memory=memory,
            )

        raise RuntimeError(
            f"Unsupported model provider: "
            f"{self.provider}"
        )

    def _mock_generate(
        self,
        prompt: str,
        context: str = "",
        memory: str = "",
    ) -> str:

        sections = [
            "ACAI Demo Model Response",
            "",
            f"Question:\n{prompt}",
        ]

        if context:

            sections.extend(
                [
                    "",
                    f"Retrieved Context:\n{context}",
                ]
            )

        if memory:

            sections.extend(
                [
                    "",
                    f"Relevant Memory:\n{memory}",
                ]
            )

        sections.extend(
            [
                "",
                "The ACAI pipeline processed "
                "the request successfully.",
            ]
        )

        return "\n".join(sections)


model_service = ModelService()
4.10 Integrating Memory into the Orchestrator
Update app/orchestrator.py:
from app.services.memory import memory_service
from app.services.model_service import model_service
from app.services.planner import planner
from app.services.retrieval import retrieval_service


class ACAIOrchestrator:

    async def process(
        self,
        message: str,
    ) -> dict:

        cleaned_message = message.strip()

        if not cleaned_message:
            raise ValueError(
                "Message cannot be empty."
            )

        plan = planner.create_plan(
            cleaned_message
        )

        retrieval_context = (
            retrieval_service.build_context(
                query=cleaned_message,
                top_k=3,
            )
        )

        memory_context = (
            memory_service.build_context(
                query=cleaned_message,
                top_k=5,
            )
        )

        response = await model_service.generate(
            prompt=cleaned_message,
            context=retrieval_context,
            memory=memory_context,
        )

        memory_service.remember(
            content=cleaned_message,
            memory_type="conversation",
        )

        return {
            "response": response,

            "plan": {
                "task_type": plan.task_type,
                "complexity": plan.complexity,
                "steps": plan.steps,
            },

            "retrieval": {
                "used": bool(
                    retrieval_context
                ),
                "context": retrieval_context,
            },

            "memory": {
                "used": bool(
                    memory_context
                ),
                "context": memory_context,
            },
        }


orchestrator = ACAIOrchestrator()
4.11 Important Improvement
The implementation above stores every message.
That is acceptable for demonstrating the pipeline, but it is not ideal for production.
A production system should use a memory policy.
For example:
Conversation
     ↓
Memory Candidate
     ↓
Importance Evaluation
     ↓
┌───────────────┐
│ Important?    │
└───────┬───────┘
        │
    ┌───┴───┐
    │       │
   YES      NO
    │       │
    ▼       ▼
 Long-Term  Temporary
 Memory     Context
4.12 Memory Policy
Add:
class MemoryPolicy:

    MIN_IMPORTANCE = 0.4

    def should_store(
        self,
        content: str,
    ) -> bool:

        score = calculate_importance(
            content
        )

        return score >= self.MIN_IMPORTANCE
Then modify MemoryService:
class MemoryService:

    def __init__(self) -> None:
        self.store = MemoryStore()
        self.policy = MemoryPolicy()

    def remember_if_useful(
        self,
        content: str,
        memory_type: str = "general",
    ) -> MemoryItem | None:

        if not self.policy.should_store(
            content
        ):
            return None

        return self.remember(
            content=content,
            memory_type=memory_type,
        )
Now the architecture becomes more selective.
4.13 Memory Testing
Create:
tests/test_memory.py
Add:
from app.services.memory import (
    MemoryService,
)


def test_memory_creation():

    service = MemoryService()

    item = service.remember(
        "The user prefers Python."
    )

    assert item.content == (
        "The user prefers Python."
    )

    assert item.memory_id


def test_memory_search():

    service = MemoryService()

    service.remember(
        "The user prefers Python for backend development."
    )

    results = service.search(
        "Python backend"
    )

    assert len(results) == 1


def test_memory_context():

    service = MemoryService()

    service.remember(
        "The project uses FastAPI."
    )

    context = service.build_context(
        "FastAPI project"
    )

    assert "FastAPI" in context


def test_memory_delete():

    service = MemoryService()

    item = service.remember(
        "Temporary memory."
    )

    deleted = service.store.delete(
        item.memory_id
    )

    assert deleted is True

    assert (
        service.store.get(
            item.memory_id
        )
        is None
    )
4.14 Test the Complete System
Run:
pytest
The test suite should now cover:
Chapter 1
API
 ↓
Chapter 2
Planner
 ↓
Chapter 3
Retrieval
 ↓
Chapter 4
Memory
4.15 End-to-End Example
First request:
"I prefer Python for backend development."
The system processes:
User Message
      ↓
Planner
      ↓
Memory Evaluation
      ↓
Memory Storage
Later request:
"What should I use for my backend?"
The pipeline becomes:
User Question
      ↓
Planner
      ↓
Memory Search
      ↓
"The user prefers Python for backend development."
      ↓
Model
      ↓
Response
This is the beginning of contextual behavior.
4.16 Memory Should Not Become a Source of Truth
A critical design principle is:
Memory ≠ Truth
A stored memory can become outdated or incorrect.
Therefore:
Memory
  ↓
Retrieved Context
  ↓
Reasoning
  ↓
Verification
  ↓
Final Answer
This is why the later verification layer is important.
4.17 Memory Evaluation
Memory systems should be evaluated independently.
Useful metrics include:
Memory Precision
Memory Recall
Retrieval Relevance
Memory Update Accuracy
Stale Memory Rate
Unnecessary Memory Rate
Latency
Storage Growth
A simple experiment can compare:
System A
No Memory

vs.

System B
Memory Enabled
Then evaluate whether memory actually improves the target tasks.
4.18 Memory Ablation
A useful ablation experiment is:
A = Model only
B = Model + Planner
C = Model + Planner + Retrieval
D = Model + Planner + Retrieval + Memory
Measure each configuration separately.
Example:
| Configuration | Task Accuracy | Context Relevance | Latency |
|---|---|---|---|
| Model only | Measure | Measure | Measure |
| + Planner | Measure | Measure | Measure |
| + Retrieval | Measure | Measure | Measure |
| + Memory | Measure | Measure | Measure |
The actual values must come from experiments; they should not be invented.
4.19 Production Upgrade Path
The prototype currently uses:
Python Dictionary
A production deployment could use:
SQLite
    ↓
PostgreSQL
    ↓
Redis
    ↓
Vector Database
Different storage systems solve different problems.
For example:
Short-Term State
→ Redis

Structured User Data
→ PostgreSQL

Semantic Memory
→ Vector Database
The correct choice depends on scale, latency, consistency, and operational requirements.
4.20 Complete Chapter 4 Architecture
                         USER
                           │
                           ▼
                      FastAPI API
                           │
                           ▼
                   ACAI Orchestrator
                           │
             ┌─────────────┼─────────────┐
             │             │             │
             ▼             ▼             ▼
          Planner       Memory       Retrieval
             │             │             │
             │             ▼             ▼
             │       Relevant Memory  Evidence
             │             │             │
             └─────────────┼─────────────┘
                           ▼
                     Model Service
                           │
                           ▼
                        Response
                           │
                           ▼
                    Memory Policy
                           │
                           ▼
                  Memory Store Update
4.21 Chapter 4 Success Criteria
Chapter 4 is complete when:
[✓] Memory data model exists
[✓] Memory store works
[✓] Memory importance can be estimated
[✓] Memory can be stored
[✓] Memory can be searched
[✓] Memory context can be constructed
[✓] Memory is integrated with the orchestrator
[✓] Memory tests pass
[✓] Retrieval and memory work together
4.22 What Comes Next?
ACAI now has:
Core
  ↓
Planner
  ↓
Retrieval
  ↓
Memory
But there is another major problem.
Different tasks may work better with different models.
For example:
Fast model
→ simple classification

Reasoning model
→ difficult reasoning

Coding model
→ programming

Vision model
→ image understanding

Local model
→ private/offline tasks
Using one model for everything may not be optimal.
Therefore the next architectural layer is:
Chapter 5 — Adaptive Model Router
The Model Router will introduce:
Task Analysis
      ↓
Model Selection
      ↓
Capability Matching
      ↓
Cost / Latency Constraints
      ↓
Selected Model
      ↓
Generation
The key principle will be:
Do not assume one model is best for every task. Measure and route according to the actual requirements.
End of Chapter 4